

AI App Gateway
AI App Gateway is a control plane for AI coding-agent traffic — Claude Code, Codex, GitHub Copilot, and Cursor — leaving your network. It gives every team one controlled entry point: who is using these tools, what they send, and what they're allowed to do, without changing how a developer actually works (they keep using their own Claude Pro/Max or ChatGPT subscription; the gateway sits in front of it).
Enterprise module — replaces Aegis
AI App Gateway supersedes the retired Aegis enforcement plane for this specific job. It is not a general tool-enforcement engine — governing what an agent's own tools may do is now the community guardrail hook plane's tool_access family. See the September 2026 Enterprise release notes for the full migration story and the breaking-change notice for old Aegis integrations.
Overview
The landing page (Operate → AI App Gateway) lists every gateway in the tenant with rolling 7-day stats — active gateways, users, sessions, requests, tokens, and blocked count — plus a table of gateways with their team, mode, policy, and status.
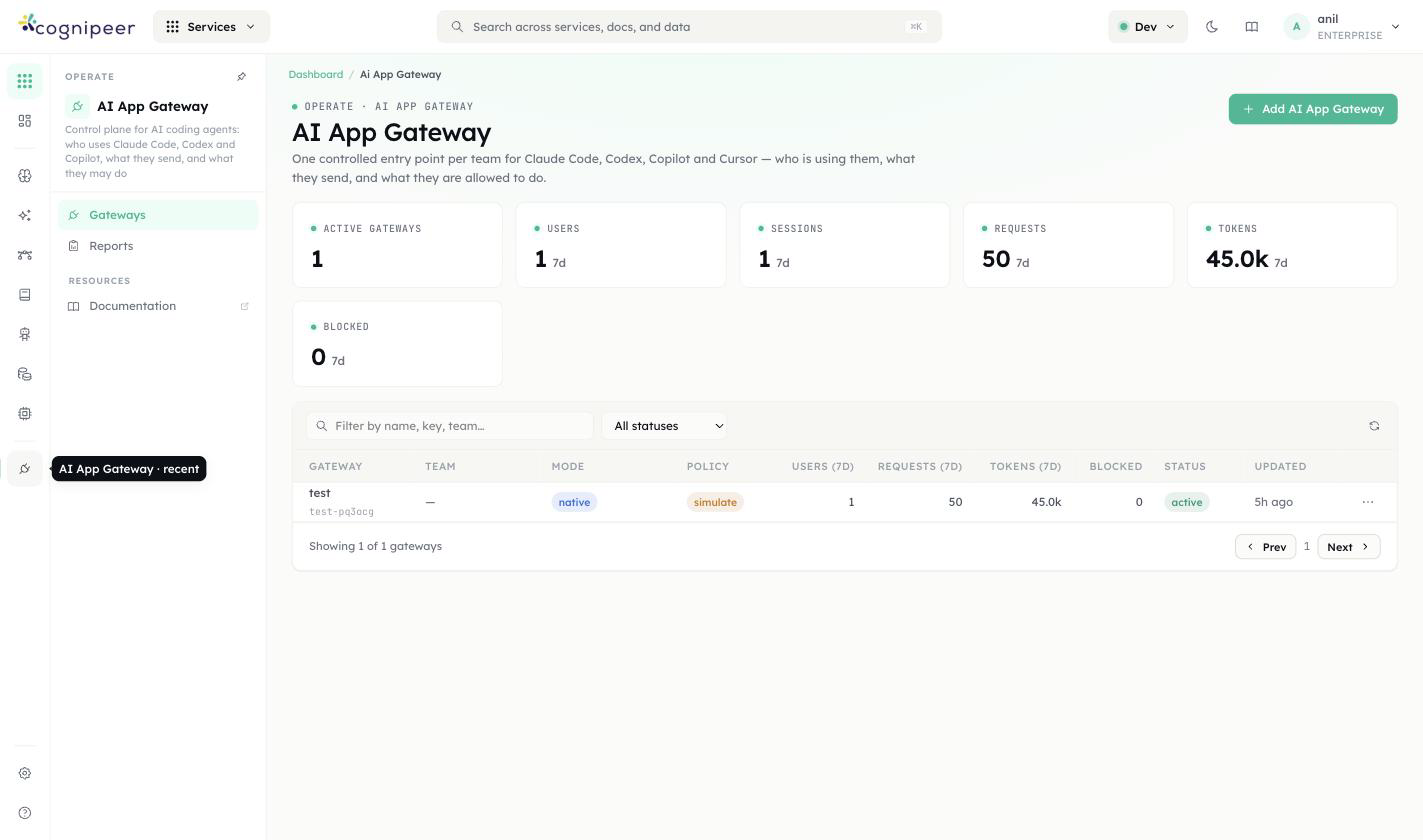
Each row shows:
| Column | Meaning |
|---|---|
| Gateway | Display name and its URL key |
| Team | Optional grouping label — reporting only, no effect on routing or policy |
| Mode | native (traffic proxied as-is) |
| Policy | The gateway's policy mode: simulate, enforce, or disabled |
| Users / Requests / Tokens / Blocked (7D) | Rolling week |
| Status | active or paused |
Click into a gateway for its detail page — Overview, Setup, Requests, Policy, Members, Settings, and Aliases tabs.
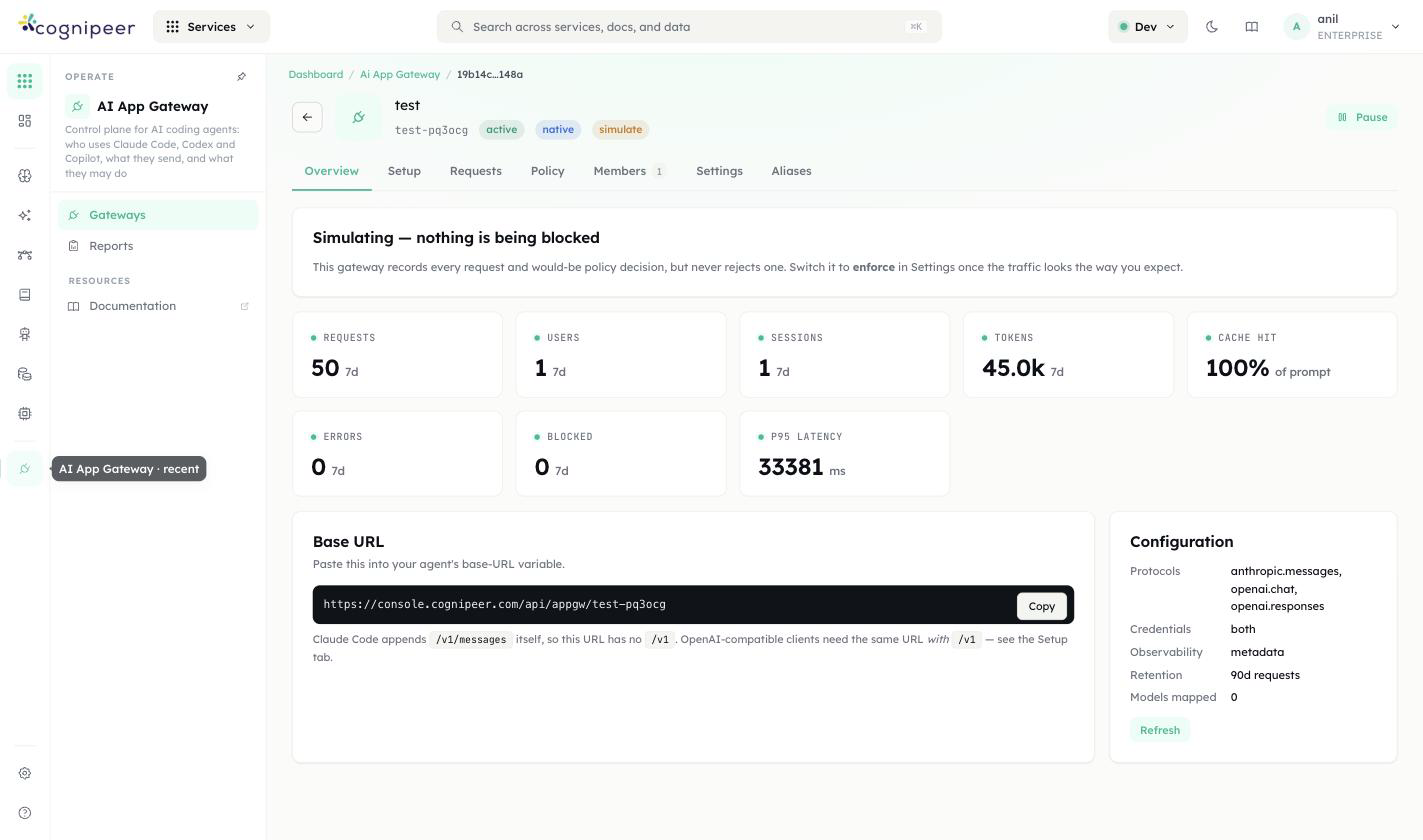
A gateway that's still in simulate mode shows a banner: "Simulating — nothing is being blocked. This gateway records every request and would-be policy decision, but never rejects one. Switch it to enforce in Settings once the traffic looks the way you expect."
The Overview tab also carries the Base URL developers paste into their client (https://<your-console>/api/appgw/<gateway-key>) and a Configuration summary: which wire protocols are accepted (anthropic.messages, openai.chat, openai.responses), whether credentials are required, observability level, and retention window.
Setup
The Setup tab generates the exact shell config for a given developer and client, from three choices — pick the three, get exactly one config block:
Who pays — see Who pays: three modes below. This is the choice most likely to break a client silently, so read it before picking a client.
Who will use it — the person the generated URL is attributed to. The identity travels in the URL itself (a per-user path segment), not in a header the client has to set. See Members and per-user URLs.
Client — searchable picker, grouped into two categories:
- Coding agents — Claude Code, Codex CLI, GitHub Copilot CLI, Goose, Aider, OpenCode, Crush, Amp
- IDEs & extensions — Cursor
One gateway can serve every client and every "who pays" mode at once, across different developers — the difference only shows up in the config block each developer pastes on their own machine. There's also a protocol-introspection endpoint any client (or a raw
curl/SDK integration) can hit directly:curl -sS "https://<your-console>/api/appgw/<gateway-key>/protocol" | jq.
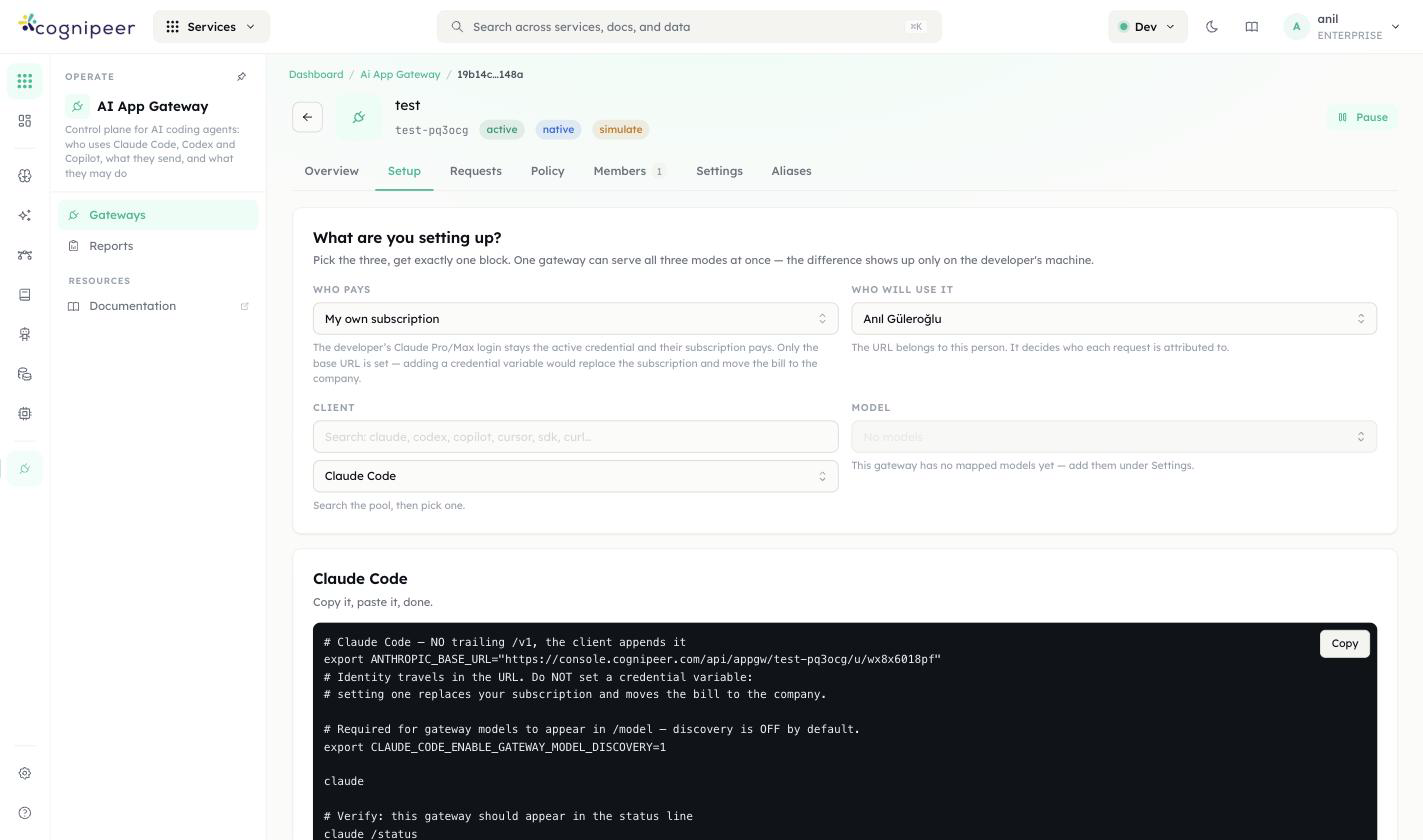
For Claude Code, the generated block looks like:
# Claude Code — NO trailing /v1, the client appends it
export ANTHROPIC_BASE_URL="https://console.example.com/api/appgw/<gateway-key>/u/<user-id>"
# Identity travels in the URL. Do NOT set a credential variable:
# setting one replaces your subscription and moves the bill to the company.

# Required for gateway models to appear in /model — discovery is OFF by default.
export CLAUDE_CODE_ENABLE_GATEWAY_MODEL_DISCOVERY=1

claude

# Verify: this gateway should appear in the status line
claude /statusOpenAI-compatible clients (Codex CLI, GitHub Copilot CLI, Cursor, and the rest of the coding-agent list) get the same base URL with a trailing /v1 — Claude Code is the one exception, since it appends /v1/messages itself. For example, Cursor's generated block is a straight paste into Cursor Settings → Models → OpenAI API Key → "Override OpenAI Base URL":
# Cursor
# Paste these in: Cursor Settings → Models → OpenAI API Key → "Override OpenAI Base URL"

Base URL:  https://console.cognipeer.com/api/appgw/<gateway-key>/u/<user-id>/v1
API key:   <GATEWAY_TOKEN>
Model:     claude-opus-5

# The key is a real credential — the organisation pays for this traffic.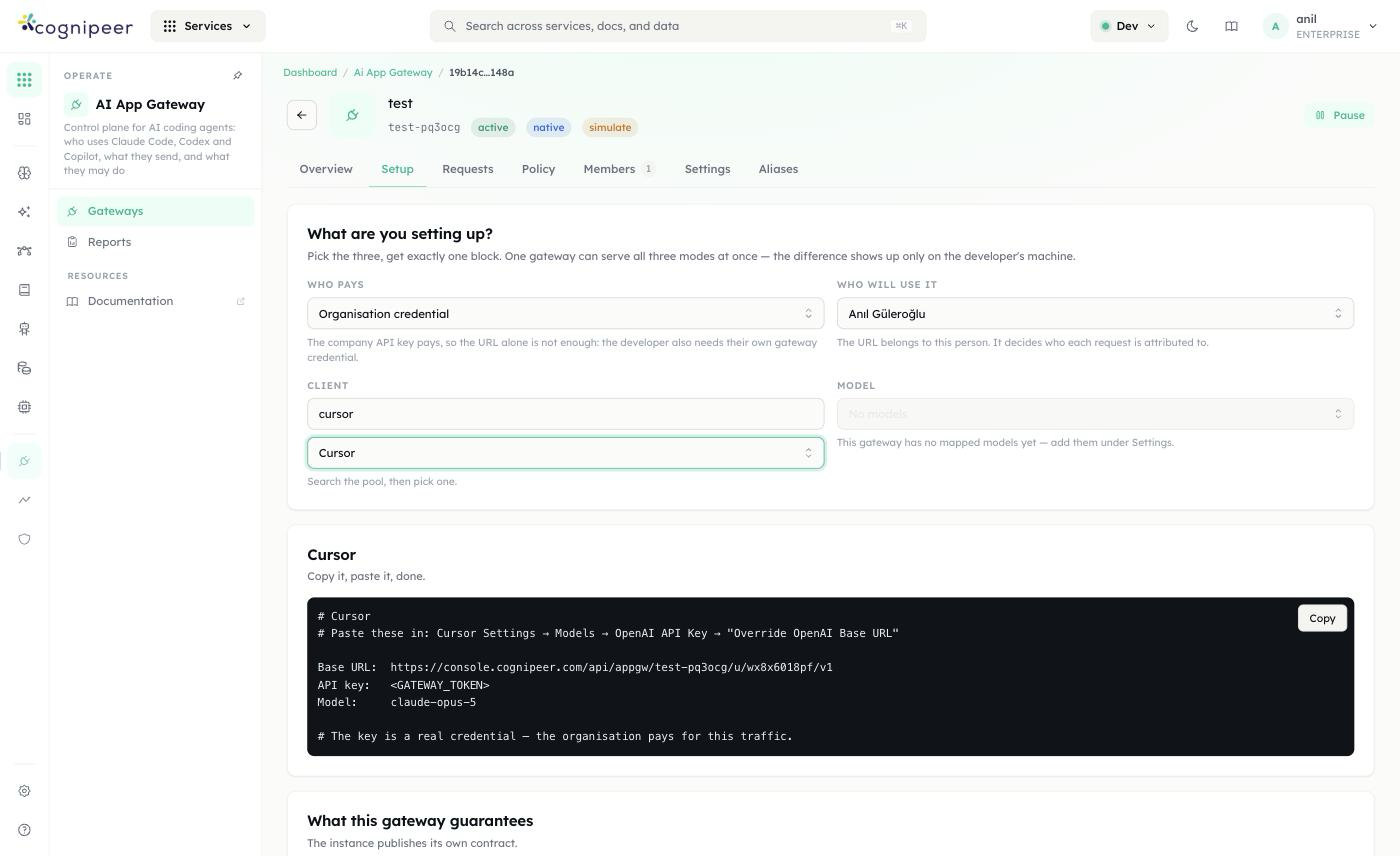
Who pays: three modes
| Mode | What it means | Extra requirement |
|---|---|---|
| My own subscription | The developer's own Claude Pro/Max (or ChatGPT) login stays the active credential — the gateway only sets the base URL. Adding a credential variable on top would replace the subscription and move the bill to the company instead. | None — base URL only. |
| Organisation credential | The company's upstream API key pays. Because the URL alone doesn't carry a secret, the developer also needs their own gateway credential (a token minted for that member, kept out of the URL). | A gateway token (<GATEWAY_TOKEN> / CGATE_TOKEN) the developer keeps in their own env, never in the URL. |
| Local model | Routes to a model the gateway has mapped from a local/self-hosted provider instead of a hosted vendor. | A model must be mapped on this gateway under Settings first — an unmapped gateway shows "No models" here. |
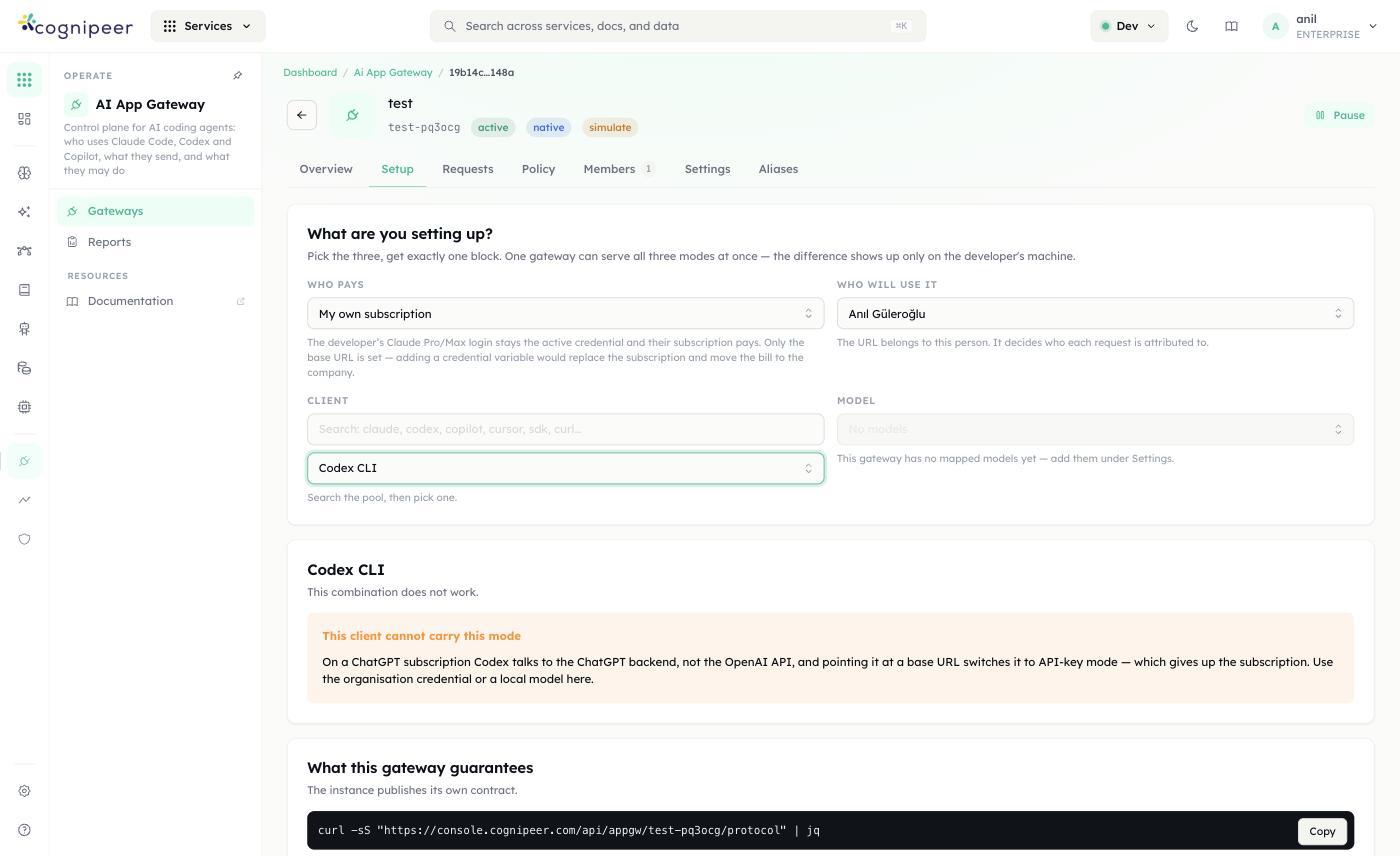
Not every client supports every mode. Codex CLI is the sharp example: on a ChatGPT subscription, Codex talks to the ChatGPT backend, not the OpenAI API — pointing it at a base URL switches it to API-key mode, which gives up the subscription. Picking Codex CLI while "Who pays" is still My own subscription surfaces an explicit error instead of a broken config:
This combination does not work. "This client cannot carry this mode" — On a ChatGPT subscription Codex talks to the ChatGPT backend, not the OpenAI API, and pointing it at a base URL switches it to API-key mode — which gives up the subscription. Use the organisation credential or a local model here.
Switching Who pays to Organisation credential immediately produces a working config instead:
# ~/.codex/config.toml
model_provider = "cgate"

[model_providers.cgate]
name     = "Cognipeer C-Gate"
base_url = "https://console.example.com/api/appgw/<gateway-key>/u/<user-id>/v1"
env_key  = "CGATE_TOKEN"
# This gateway serves chat completions, not the Responses API.
wire_api = "chat"
requires_openai_auth = false

# export CGATE_TOKEN="<GATEWAY_TOKEN>"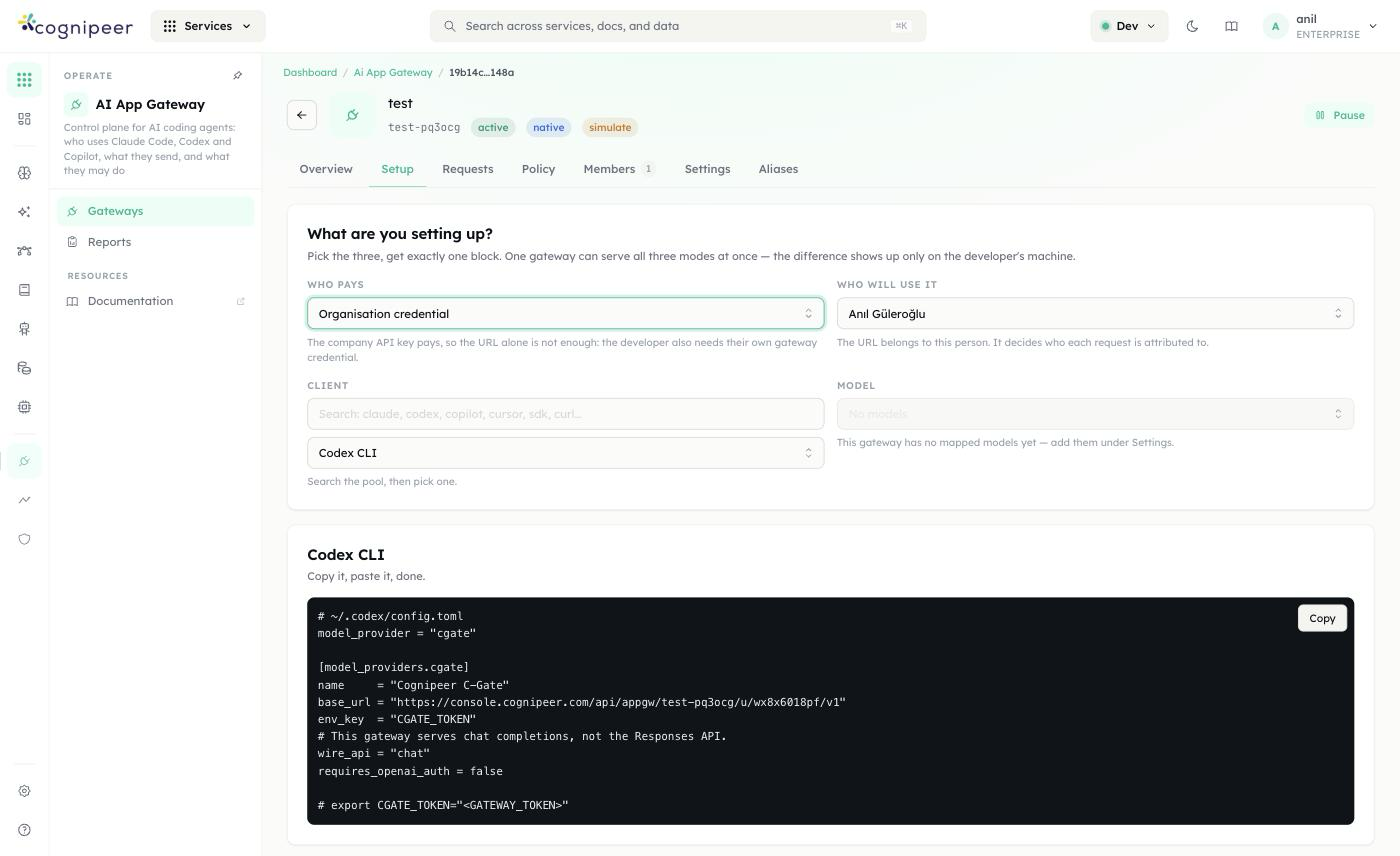
The takeaway: before troubleshooting a client integration, check Who pays first — a client that looks broken is very often just pointed at a mode it can't carry.
Members and per-user URLs
The Members tab is where multi-user access is actually granted — every row here is one developer with their own attributed URL, independent of who administers the gateway.
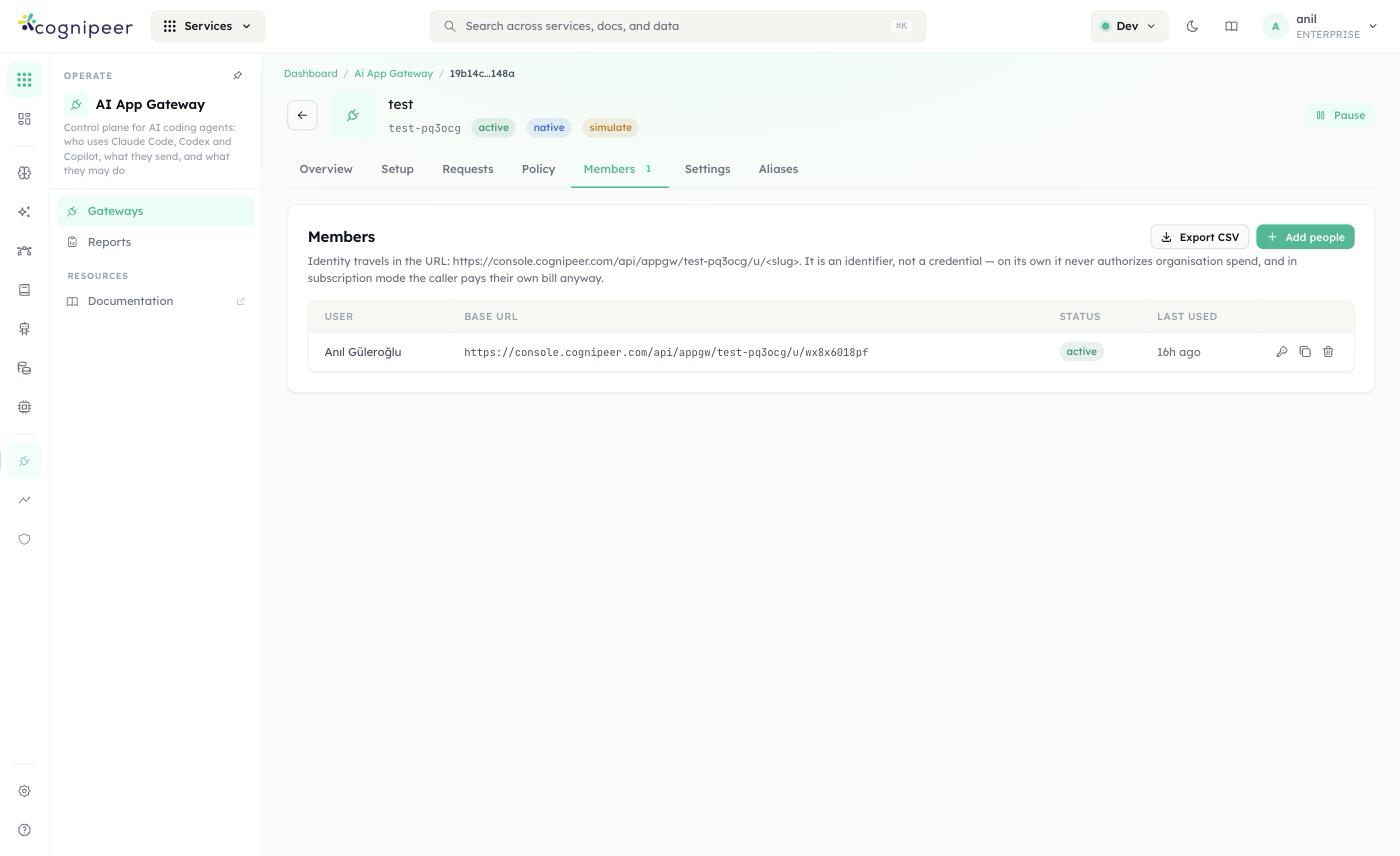
- Add people invites additional developers to this gateway; Export CSV dumps the member list (user, base URL, status, last used) for provisioning or audit.
- Each member's row shows their Base URL — the same
.../u/<slug>pattern from Setup, generated per person rather than typed by hand — plus Status (active/revoked) and Last Used. - The explanatory copy on this tab makes the security model explicit: "Identity travels in the URL:
https://<your-console>/api/appgw/<gateway-key>/u/<slug>. It is an identifier, not a credential — on its own it never authorizes organisation spend, and in subscription mode the caller pays their own bill anyway." In other words: a leaked per-user URL under My own subscription or Local model mode attributes traffic to that person but doesn't hand out spend; only Organisation credential mode pairs the URL with an actual secret (the gateway token), and that token is never embedded in the URL itself. - Row actions (icons on the right) let an admin regenerate a member's URL/credential, copy it, or revoke access — revoking flips Status without deleting the member's request history.
This is also how the gateway supports many developers on one gateway without them sharing a credential: each person gets their own row, their own URL, their own token when one applies, and their own line in Requests — so policy decisions, blocks, and spend are all attributable per person even though they're all going through the same <gateway-key>.
Policy
Detects and refuses — never rewrites
The gateway's enforcement model is deliberately narrow: it can block a request, never silently rewrite one. Anthropic's gateway contract is explicit that redacting request bodies breaks the capability pairing Claude Code relies on, and redacting file contents an agent just read would make it write [REDACTED] back into your repository. Response-side checks are audit-only for the same reason a stream can't be blocked mid-delivery — by the time bytes can be classified, they've already reached the user.
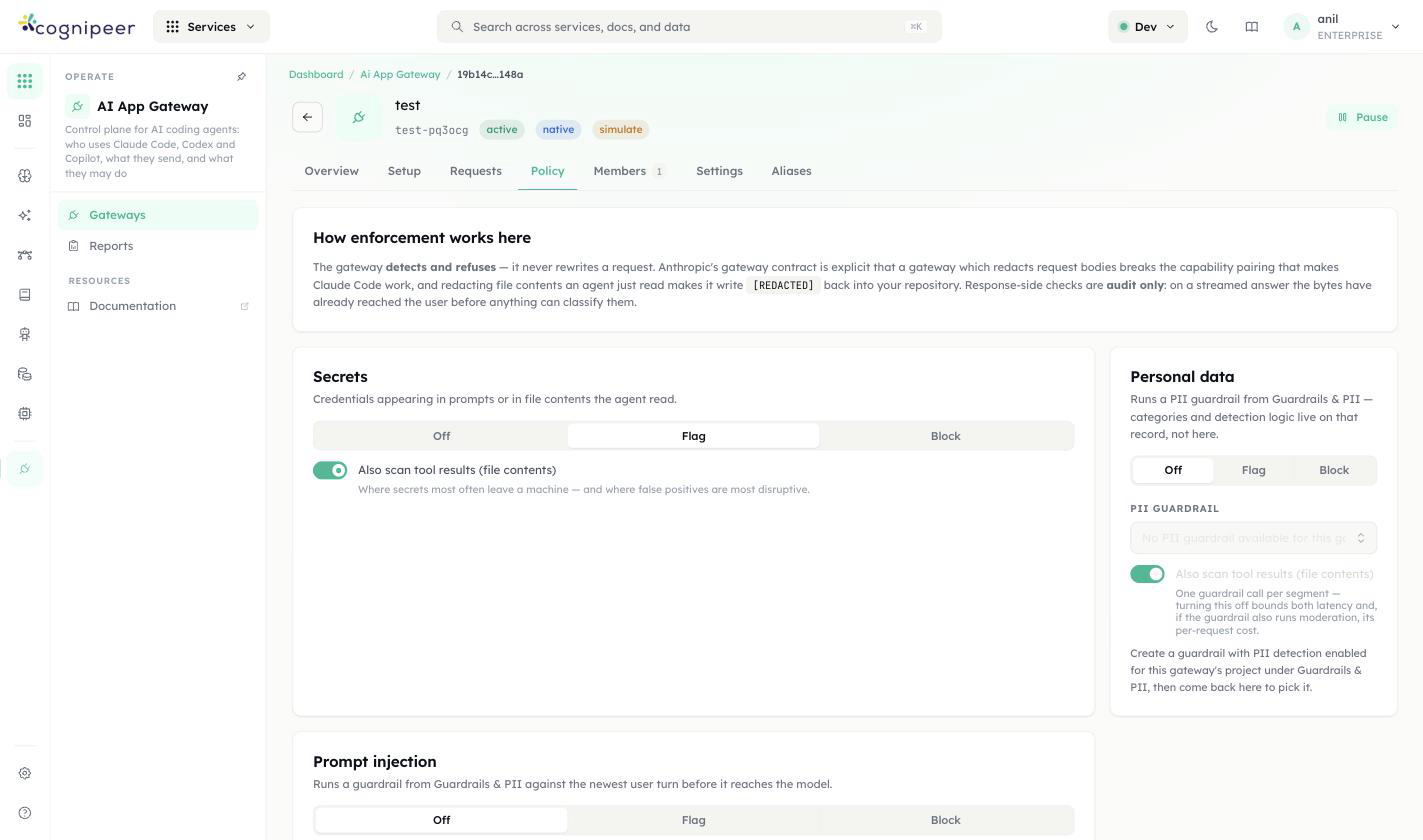
Three independent checks, each Off / Flag / Block:
- Secrets — credentials appearing in prompts or in file contents the agent read. A separate toggle extends the scan to tool results (file contents), since that's both where secrets most often leave a machine and where false positives are most disruptive.
- Personal data — delegates to a PII guardrail from Guardrails & PII rather than reimplementing detection here; you pick which guardrail to run from a dropdown once one exists for this gateway's project. The same "also scan tool results" toggle applies — each call costs one guardrail evaluation per segment, so turning it off bounds both latency and, if that guardrail also runs moderation, its per-request cost.
- Prompt injection — runs a guardrail against the newest user turn before it reaches the model.
Requests
Every request is logged with its policy decision and which rule(s) fired, filterable by agent, status, decision, and date range, with an optional live tail and session grouping.
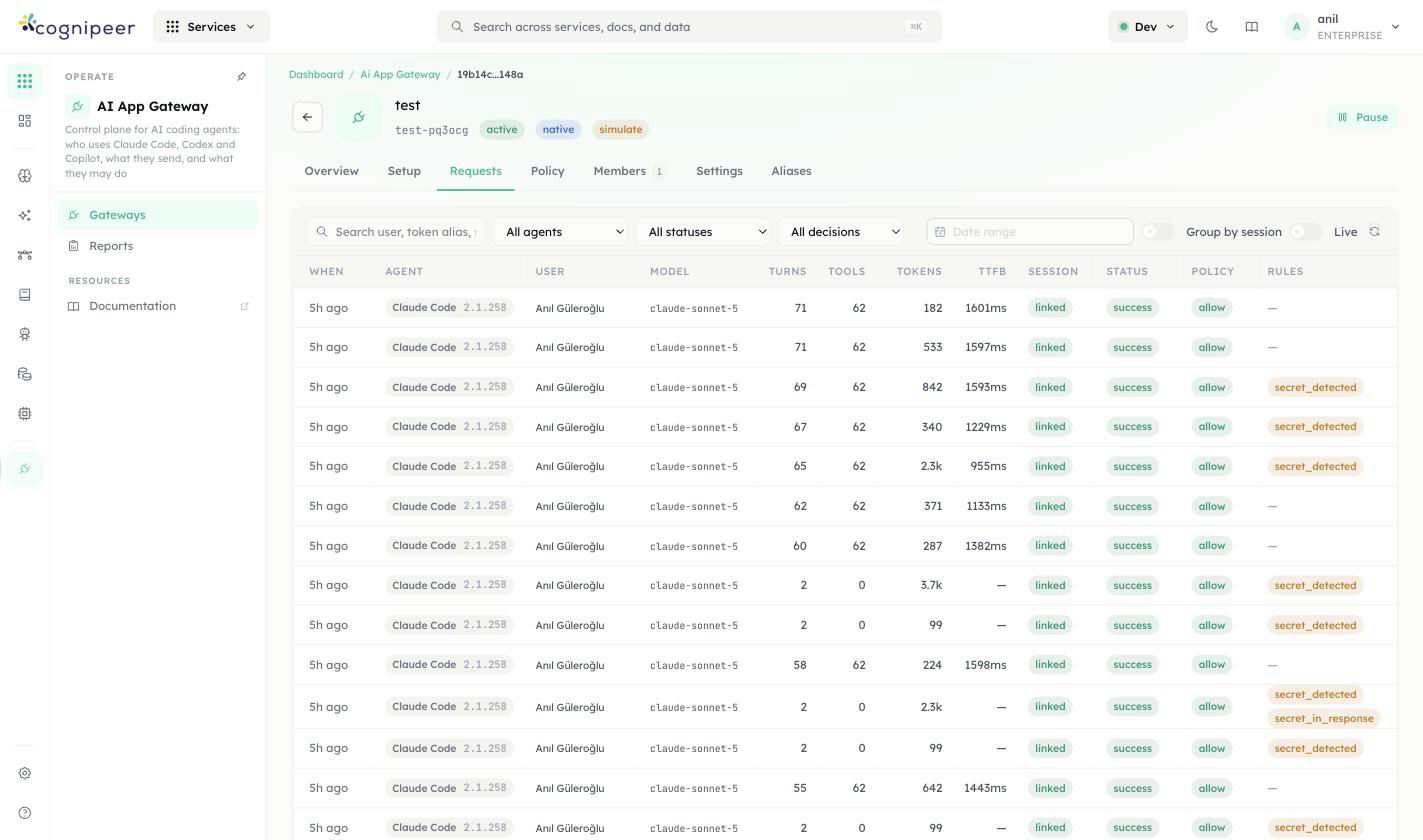
Columns: when, agent (with client version, e.g. Claude Code 2.1.258), user, model, turn/tool counts, tokens, time-to-first-byte, session (linked), status, policy decision (allow / block), and the specific rule matched (e.g. secret_detected, secret_in_response) when one did. This is the same turn-grouped request/response viewer the community edition ships for Model Hub and Tracing.
Settings
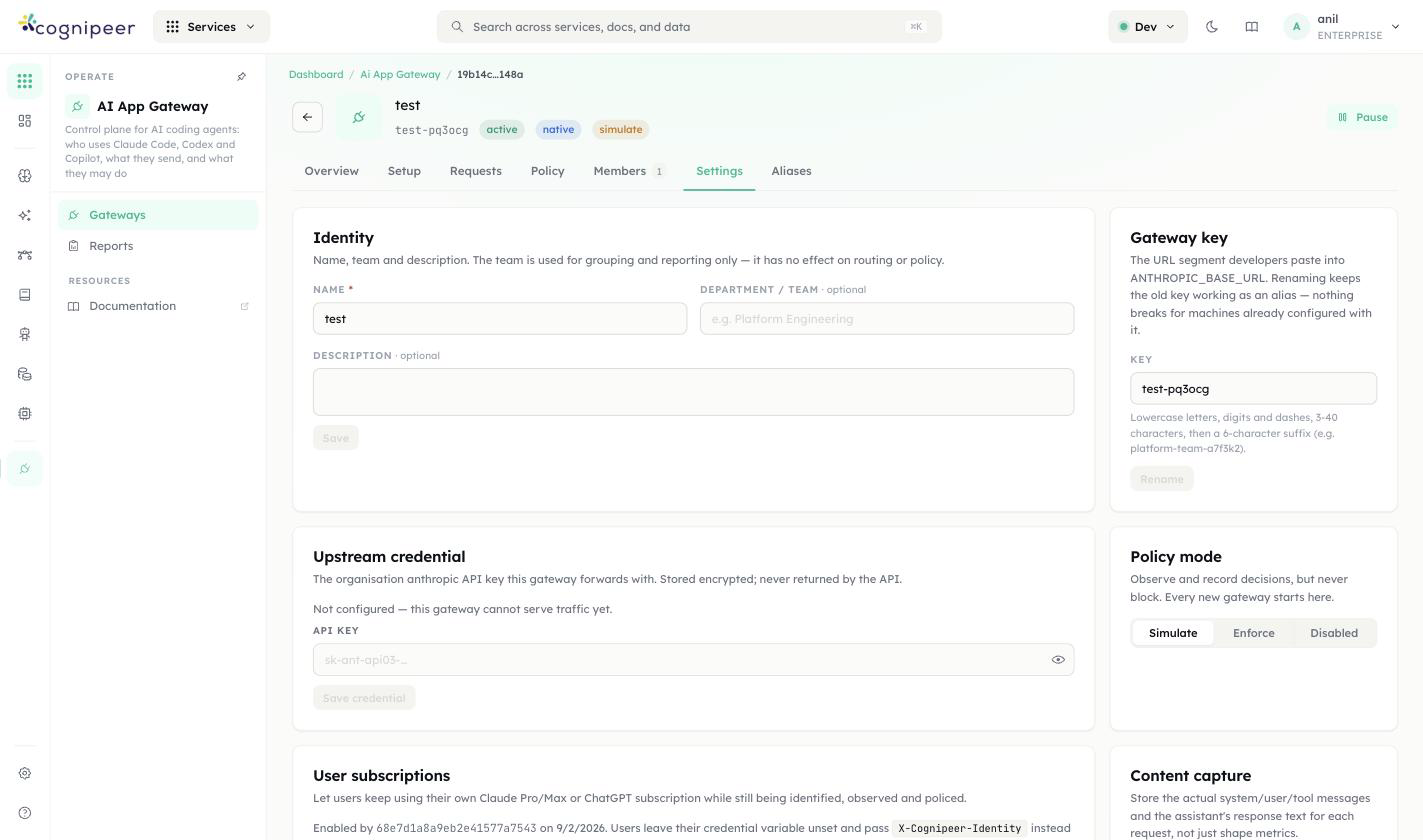
- Identity — name, optional team, optional description. The team is reporting-only.
- Gateway key — the URL segment developers paste into
ANTHROPIC_BASE_URL. Renaming keeps the old key working as an alias (tracked under the Aliases tab), so nothing breaks for machines already configured with it. - Upstream credential — the organization's Anthropic API key this gateway forwards with, stored encrypted and never returned by the API. A gateway with no credential configured cannot serve traffic yet.
- Policy mode — Simulate (observe and record decisions, but never block — every new gateway starts here), Enforce, or Disabled.
- User subscriptions — lets developers keep using their own Claude Pro/Max or ChatGPT subscription while still being identified, observed, and policed: they leave their credential variable unset and the gateway reads identity from the URL instead.
- Content capture — whether to store the actual system/user/tool messages and the assistant's response text per request, versus shape-only metrics.
See Members and per-user URLs above for how the Members tab grants and attributes per-developer access.
Related
- Guardrails — the community guardrail hook plane, including the
tool_accessfamily that replaces Aegis's tool-enforcement role - Enterprise release notes: AI App Gateway
- Agent Tracing — the turn-grouped request/response viewer this module's Requests tab builds on
Step by step: connect an OpenAI-compatible client
Console speaks the OpenAI wire protocol. Anything that lets you set a base URL and an API key — Open WebUI, LiteLLM, Cursor, the official openai SDKs — can call your models through Console instead of calling a provider directly. The traffic then picks up project scoping, guardrails, usage accounting and spend attribution on the way through.
This page goes from a fresh tenant to a working client: pick the project, read a model key, mint a token, verify with curl, then point the client at it. The control plane is a community feature; no Enterprise licence is involved.
What you end up with
Three values. Every client on this page wants the same three.
| Setting | Value |
|---|---|
| Base URL | https://<your-console-host>/api/client/v1 — no trailing slash, no extra /v1, not /api/v1 |
| API key | a Console API token: cpeer_ followed by 64 hex characters |
| Model name | the model's key from Model Hub — not its display name, not the provider's model id |
The token carries the tenant and the project. Neither is ever read from the request body, so a client that is configured once keeps talking to the same project until you replace the token.
Prerequisites
- A Console account with the role
owner,admin,project_adminoruser— those four roles may mint tokens. - At least one model of category
llmin the target project. If you have none, work through Create your first model first. - The token owner needs Model Hub
readandwrite: listing models is aGET(read), and a chat completion is aPOST(write). RBAC is evaluated against the user who created the token. See Authentication for the role table.
Step 1 — Select the project
The token you are about to create is bound to whichever project is active in the browser at that moment, permanently. Set it first.
The project selector sits in the top bar and shows the active project's name; its menu is headed Switch project.
Step 2 — Read the model key
Open Model Hub (/dashboard/models). The sub-nav has an LLM filter if the list is long.
In the Name column, each row shows the display name in bold with a small monospace string underneath. That string is the model key, and it is the only value model accepts.
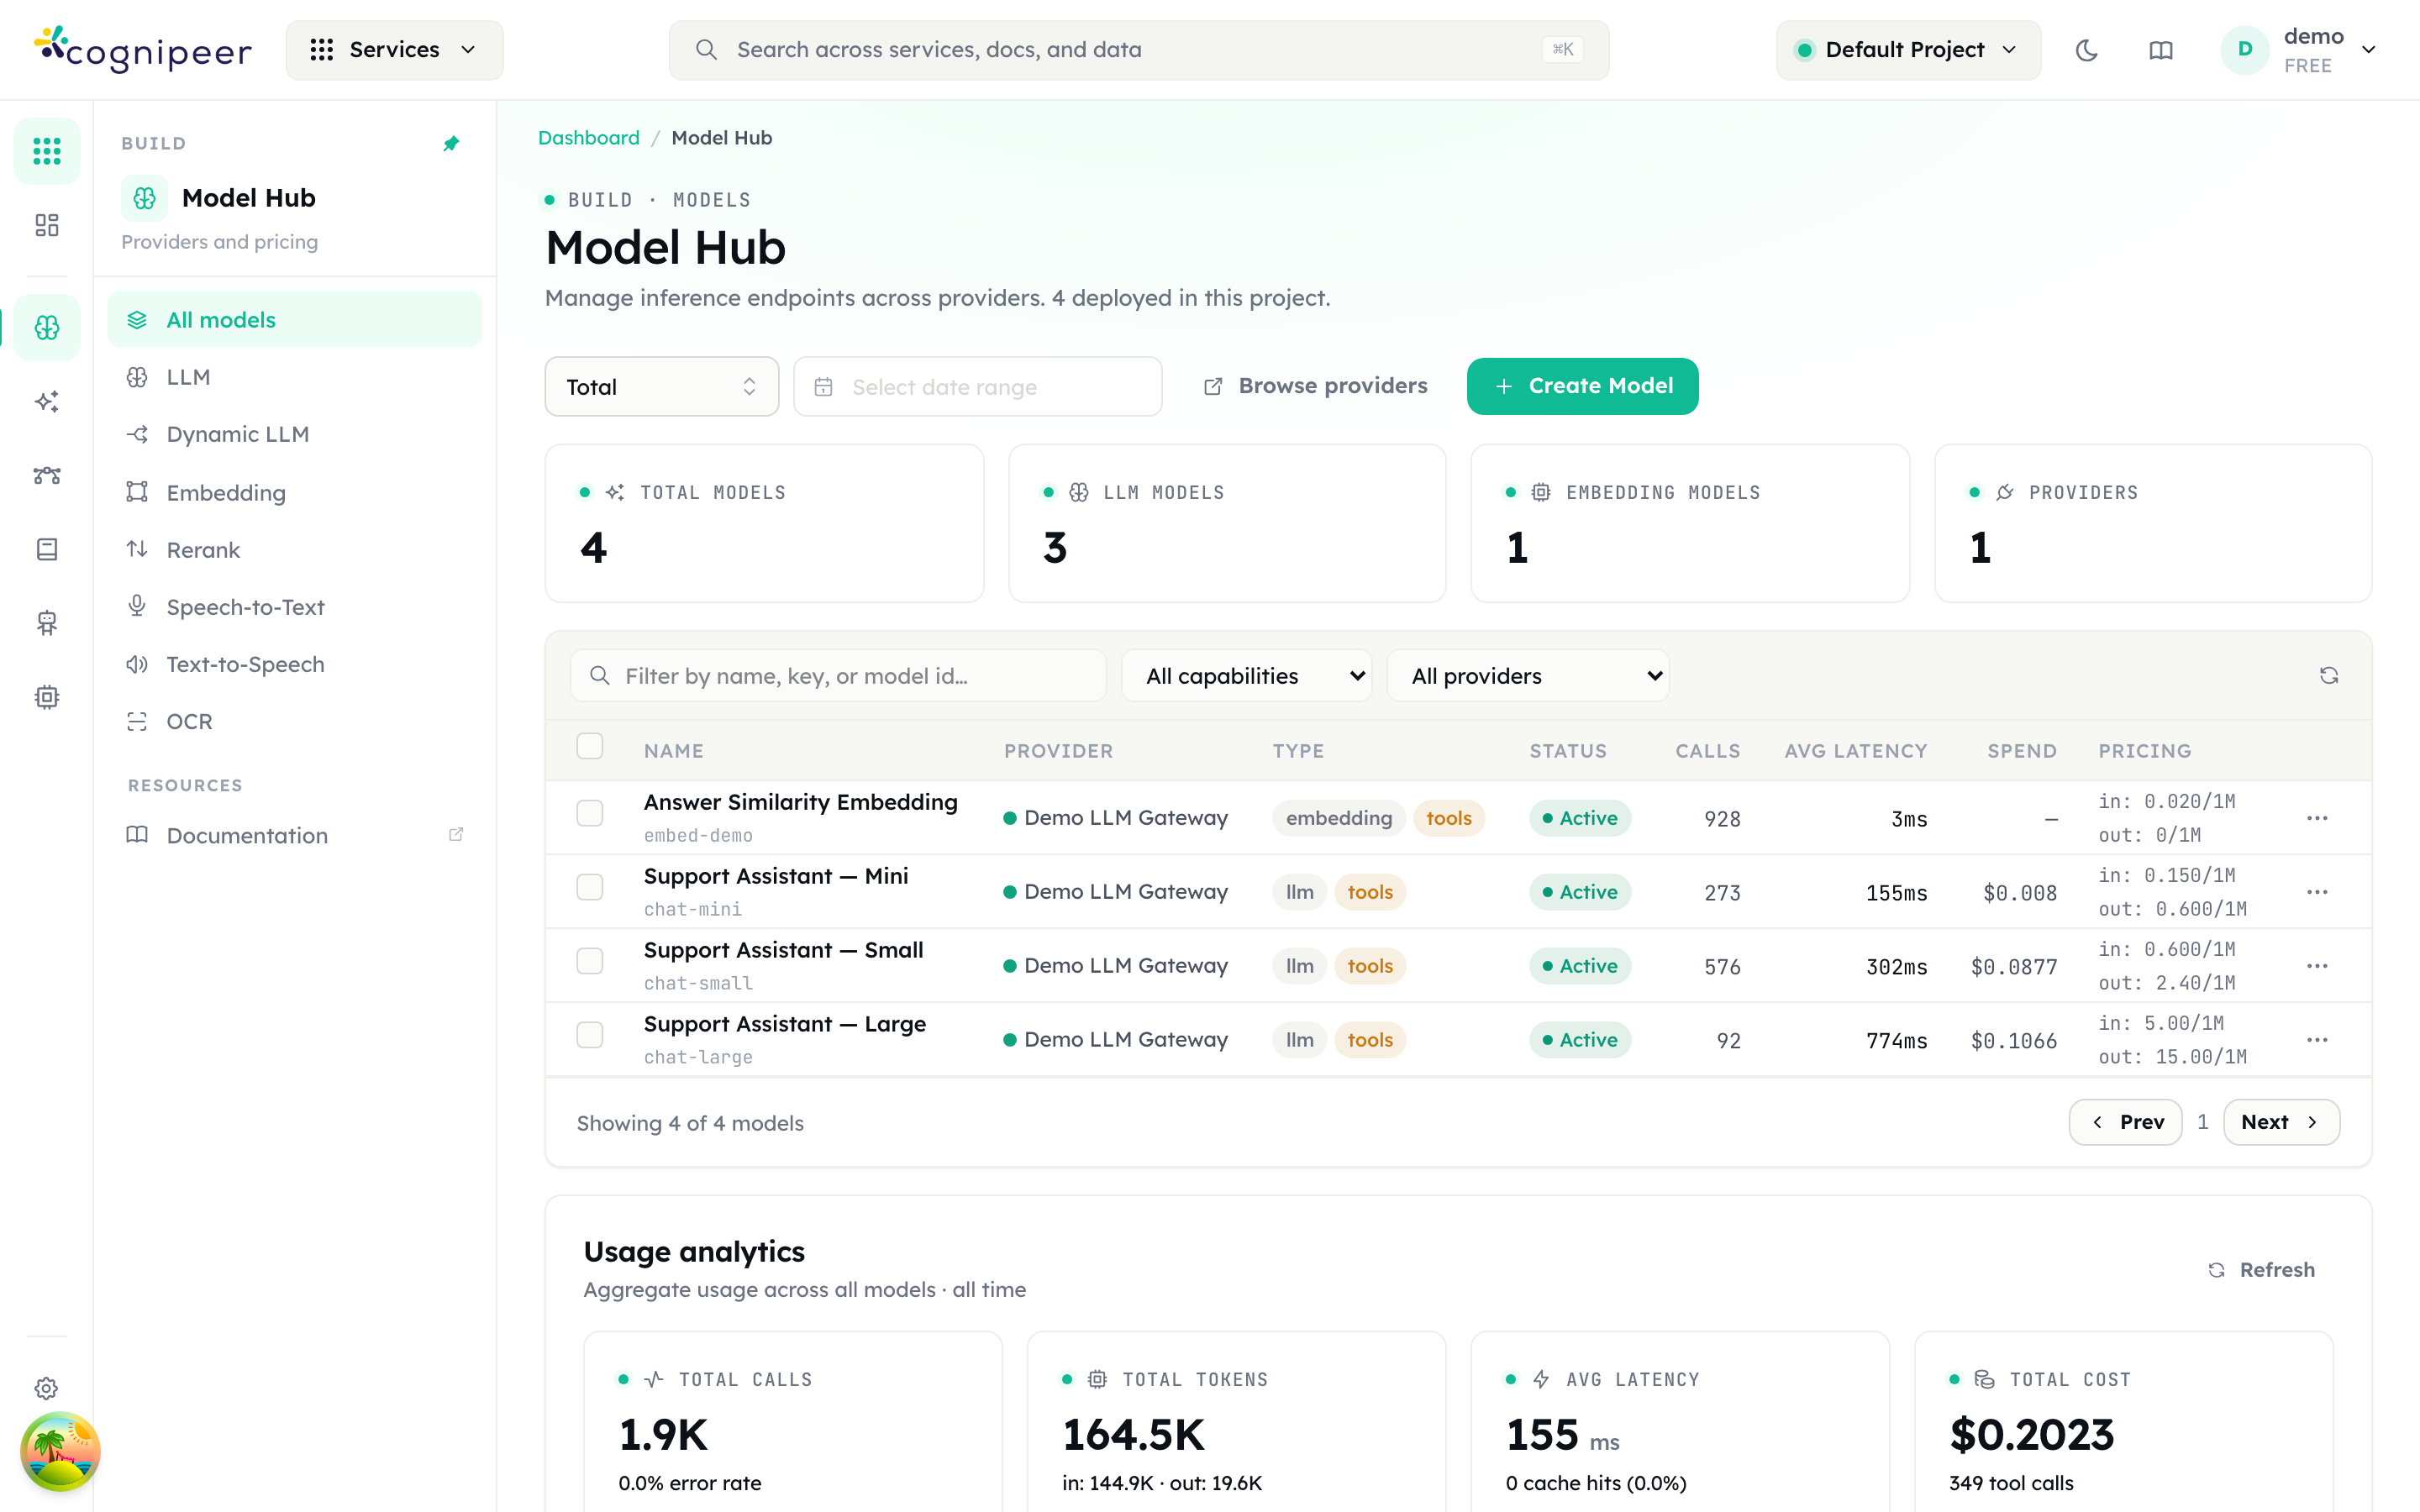
Look at the Name column: "Support Assistant — Mini" is the display name, chat-mini underneath it is the key you send as model. The Type column shows the category — you want llm rows for chat completions.
Step 3 — Create the API token
Open the account menu in the top bar and choose Settings. In the left nav under Settings, choose API Tokens (/dashboard/tokens, page eyebrow "Configure · API Tokens").
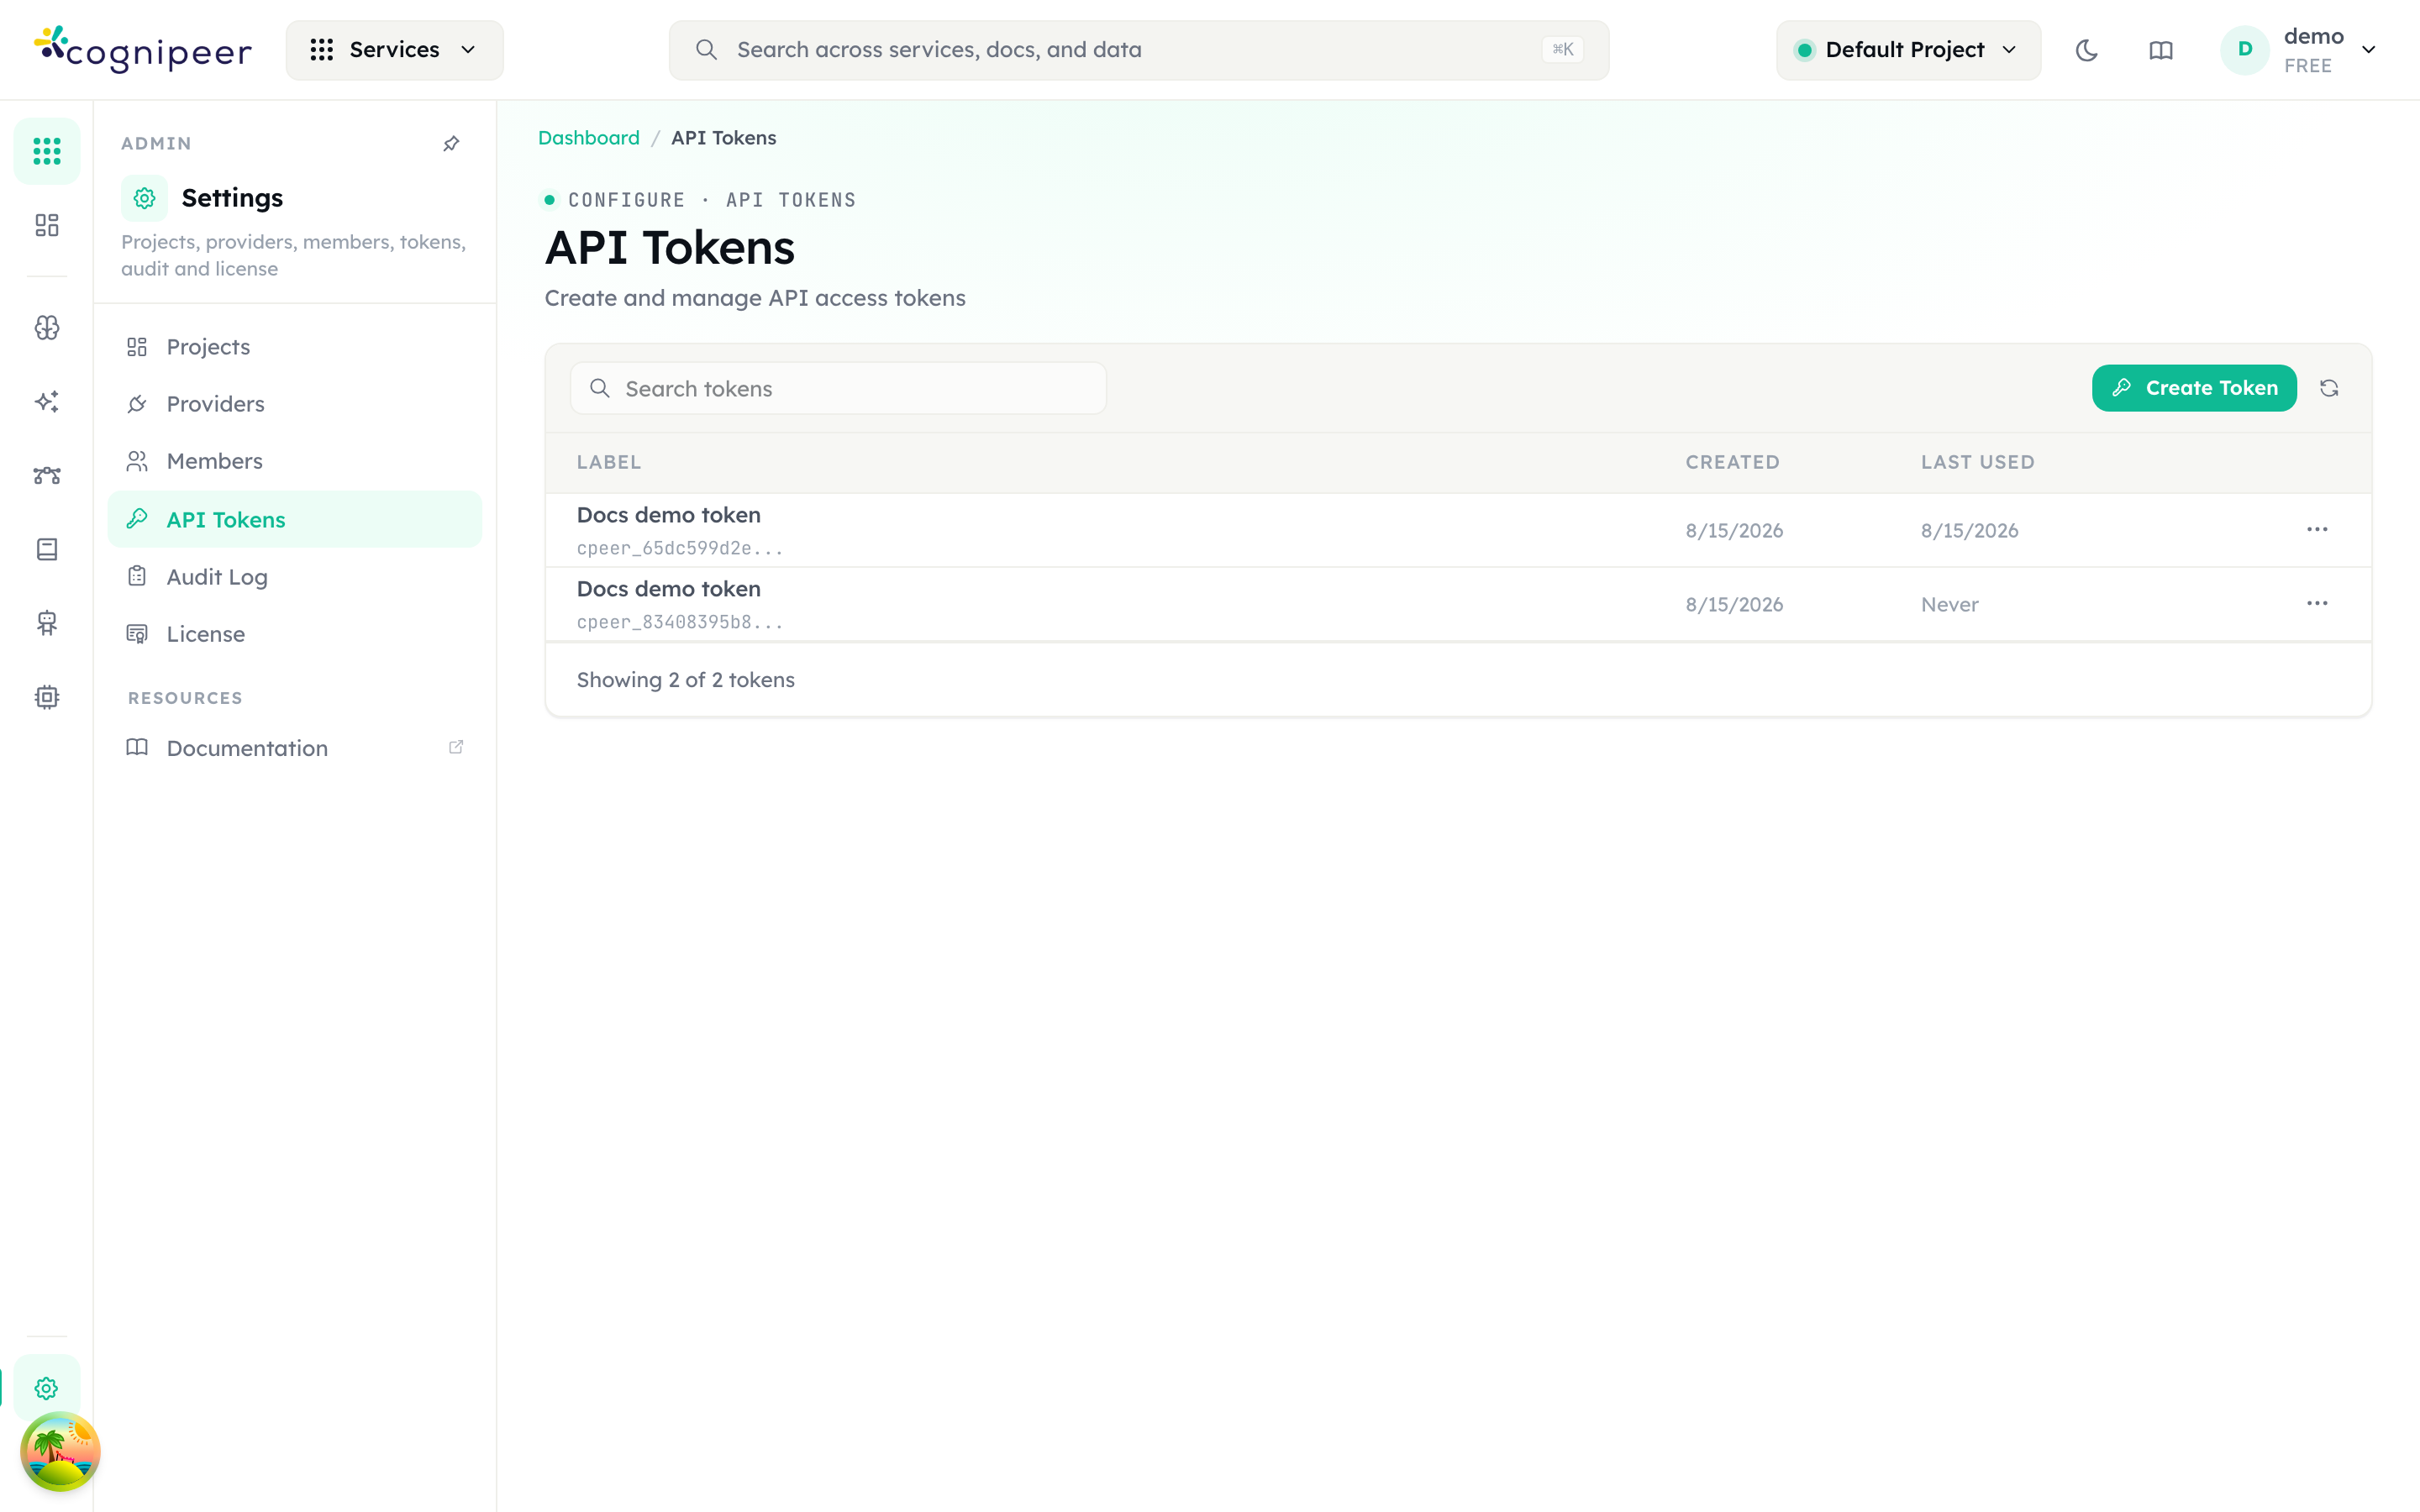
Look at the top right of the grid for the Create Token button, and at the grid rows: each shows the label with a truncated cpeer_… prefix underneath. Only a SHA-256 hash and that 16-character prefix are stored — the full secret is not recoverable from this screen.
- Select Create Token.
- Fill in Token Label — minimum 3 characters. Name it after the client ("Open WebUI", "LiteLLM prod"). The grid shows only Label, Created and Last Used, so the label is the only thing that tells one token from another once the secret is gone.
- Select Create Token in the footer.
- The panel switches to Your New API Token. Under the orange Important! alert, Your API Token: holds the secret. Copy it now — the alert is literal:
This is the only time you'll see this token. Make sure to copy it now! - Select I've Copied My Token.
Deleting a token here is immediate in the database but not instant on the wire — see the gotchas below.
Step 4 — Verify from a shell
Before touching a client, prove the three values work. Replace the host and the token.
export COGNIPEER_BASE_URL="https://console.example.com/api/client/v1"
export COGNIPEER_API_KEY="cpeer_..."

curl -s "$COGNIPEER_BASE_URL/models" \
-H "Authorization: Bearer $COGNIPEER_API_KEY" | jq '.data'The response carries both an OpenAI-shaped list and Console's own richer list:
{
  "object": "list",
  "data": [
    { "id": "chat-mini", "object": "model", "created": 1755216000, "owned_by": "my-provider" }
  ],
  "models": [ { "key": "chat-mini", "name": "Support Assistant — Mini", "category": "llm", "…": "…" } ]
}data[].id is the model key. owned_by is the provider key, or cognipeer when the model has no provider. OpenAI clients read data and ignore models; models carries the full Console model record, with any provider credentials in settings masked.
GET /models returns every category — embeddings, rerankers, STT, TTS and OCR models sit in the same list. Narrow it with a query parameter when you are driving it yourself:
curl -s "$COGNIPEER_BASE_URL/models?category=llm" \
-H "Authorization: Bearer $COGNIPEER_API_KEY" | jq -r '.data[].id'Then send a completion:
curl -s "$COGNIPEER_BASE_URL/chat/completions" \
  -H "Authorization: Bearer $COGNIPEER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "chat-mini",
    "messages": [{ "role": "user", "content": "Say hello in one sentence." }]
}'The non-streaming response is a standard chat.completion object plus one non-standard top-level field, request_id. Keep it: it is the correlation key for the request in Console's logs.
Streaming is server-sent events terminated by data: [DONE], with X-Request-Id on the response headers:
curl -N "$COGNIPEER_BASE_URL/chat/completions" \
  -H "Authorization: Bearer $COGNIPEER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "chat-mini",
    "stream": true,
    "messages": [{ "role": "user", "content": "Count to five." }]
}'If all three calls work, every client below is a configuration exercise.
Step 5 — Point a client at it
Python — official openai SDK
from openai import OpenAI

client = OpenAI(
    base_url="https://console.example.com/api/client/v1",
    api_key="cpeer_...",
)

resp = client.chat.completions.create(
    model="chat-mini",                     # the Model Hub key
    messages=[{"role": "user", "content": "Say hello in one sentence."}],
)
print(resp.choices[0].message.content)

# Streaming. Guard on `choices` — the terminal usage frame carries an empty
# `choices` array, exactly as OpenAI's own stream does.
for chunk in client.chat.completions.create(
    model="chat-mini",
    messages=[{"role": "user", "content": "Count to five."}],
    stream=True,
):
    if not chunk.choices:
        continue
    delta = chunk.choices[0].delta.content
    if delta:
print(delta, end="", flush=True)JavaScript / TypeScript — official openai SDK
import OpenAI from 'openai';

const client = new OpenAI({
  baseURL: 'https://console.example.com/api/client/v1',
  apiKey: process.env.COGNIPEER_API_KEY,
});

const resp = await client.chat.completions.create({
  model: 'chat-mini',
  messages: [{ role: 'user', content: 'Say hello in one sentence.' }],
});
console.log(resp.choices[0].message.content);For Console-specific features beyond the OpenAI surface — RAG modules, web search, agents — use the Console SDK rather than the openai package.
LiteLLM
Console is an openai/-prefixed provider to LiteLLM. Map each Console model key to whatever public name you want your callers to use.
# config.yaml
model_list:
  - model_name: gpt-4o-mini                      # the name your callers send
    litellm_params:
      model: openai/chat-mini                    # openai/<Console model key>
      api_base: https://console.example.com/api/client/v1
      api_key: os.environ/COGNIPEER_API_KEY

  - model_name: text-embedding-3-small
    litellm_params:
      model: openai/embed-demo
      api_base: https://console.example.com/api/client/v1
api_key: os.environ/COGNIPEER_API_KEYexport COGNIPEER_API_KEY="cpeer_..."
litellm --config config.yamlDeclare models explicitly rather than relying on model discovery — that keeps non-chat categories out of your chat namespace, which is the failure mode described under Gotchas.
Open WebUI
Open WebUI can be configured at start-up or through its admin screens. Both do the same thing.
At start-up:
docker run -d -p 3000:8080 \
  -e OPENAI_API_BASE_URL="https://console.example.com/api/client/v1" \
  -e OPENAI_API_KEY="cpeer_..." \
  -v open-webui:/app/backend/data \
  --name open-webui --restart always \
ghcr.io/open-webui/open-webui:mainThrough the UI — the labels below belong to Open WebUI's own admin interface, not Console's, and Open WebUI has moved them between releases; if a name does not match your build, look for the equivalent section:
- Admin Panel → Settings → Connections, in the OpenAI API section, add a connection.
- API Base URL =
https://console.example.com/api/client/v1. No trailing slash and no extra/v1. - API Key = the
cpeer_token. - Use the connection's verify control to confirm Open WebUI can reach
/models, then save and reload the page. - Admin Panel → Settings → Models — hide every entry that is not an LLM. Console returns the whole model catalogue and Open WebUI lists all of it; an embedding or TTS model left visible will fail the moment a user picks it.
- Optional: point Admin Panel → Settings → Documents (embeddings) and Admin Panel → Settings → Audio (speech-to-text and text-to-speech) at the same base URL and key, choosing the Console keys of your
embedding,sttandttsmodels. Those hit/embeddingsand/audio/transcriptions,/audio/translations,/audio/speechrespectively.
Gotchas
Read these before filing a bug
/modelsreturns every category. Embedding, rerank, STT, TTS and OCR models appear alongside LLMs. Selecting one for chat returns HTTP 500 withModel is not configured for chat completions. Hide non-LLM entries in the client, or filter with?category=llmwhen you drive the endpoint yourself.- An unknown model key is a 500, not a 404. The body is
{"error":{"message":"Model with key <key> not found","type":"server_error"}}. A typo in the model name looks like a server fault. Check the key againstGET /modelsfirst. - The
Bearerprefix is case-sensitive. The edge check matchesBearerexactly;bearer cpeer_…returns 401 before the token is ever looked up. The message isMissing or invalid Authorization header. Use: Bearer <token>. - Parameters outside the forwarded set are dropped. The control plane forwards a fixed set of request parameters; anything outside it is discarded unless the model has Forward unrecognised caller parameters enabled (
settings.allowUnknownPassthrough, off by default). Dropped by default:n,logit_bias,user,logprobs. usageonly rides on a stream when you ask for it. Sendstream_options: {"include_usage": true}and the counts arrive on a final{"choices": [], "usage": {…}}frame, as OpenAI specifies. Without it, no frame carriesusage— billing and quota are still accounted for server-side. A model that listsstream_optionsunder Also reject these, or has it auto-detected as unsupported, suppresses the frame, and client-side token counters then read zero.- Streaming stays on when your request carries
tools. If an upstream genuinely cannot stream tool calls, setdisableStreamingWithTools: truein that model's Settings JSON; the control plane then answers a streamed tool-carrying request in a single frame for that model only. - Token authentication is cached for 60 seconds. A deleted or newly permission-changed token can keep working for up to a minute. Expiry is re-checked on every request and is not subject to the cache.
- There is no legacy
/completionsendpoint. Only/chat/completions. Clients that fall back to the text-completion API will 404. /api/models/v1is a dead prefix. It appears in some older material. It is allowlisted but nothing serves it. The base URL is/api/client/v1.- A token is bound to one project. It was fixed at creation time from the active project and cannot be repointed. A client that needs a second project needs a second token.
- Upstream 4xx responses keep their real status. A provider rejecting a parameter reaches your client as a 400, not a masked 500, so a permanent failure stops looking like a transient one. Retry on 429 and on 5xx; do not retry the other 4xx codes. Console does not currently set a
Retry-Afterheader on 429s, so use your client's own backoff rather than waiting for one. - A blocked guardrail returns HTTP 400 with a non-standard body:
{"error":{"type":"guardrail_block","message":…,"action":…,"findings":[…],"guardrail_key":…}}. Generic OpenAI clients will surface it as an opaque bad request. See Guardrails.
Where to go next
- Chat Completions API and Embeddings API for the full request and response reference.
- Model Inference for how a request is resolved, retried and priced.
- Model Hub for the model list, detail tabs and runtime settings.
- Authentication for the token format and user roles.
- API Reference Overview for everything outside the OpenAI-compatible surface.